Oct 28, 2026
php2shell: anatomy of two PHP lifecycle bugs
How out-of-memory corruption and stale worker state became two critical PHP RCEs and why the original exploit theory got it wrong.
 Keiran Smith
Most of the effort we put into securing a PHP app happens too late to matter for this one. We harden controllers, sanitise input, argue about middleware, and the whole time the interpreter has already read the request body and run a stack of feature code on our behalf. php2shell lives in that gap, before a single line of userland runs. It is two unauthenticated RCEs, CVE-2026-109618 and CVE-2026-109619, both scored CVSS v4.0 9.2, reported by Wiz Research with credit shared across a handful of independent reporters and the PHP core team. Neither is really a bug in one function. Both come down to how PHP treats the memory of a request that dies badly, so I want to walk through each of them, because the explanation doing the rounds before disclosure (the one I believed) had it wrong.
Worth pinning these down separately, because almost every early writeup, mine among them, ran the two together.

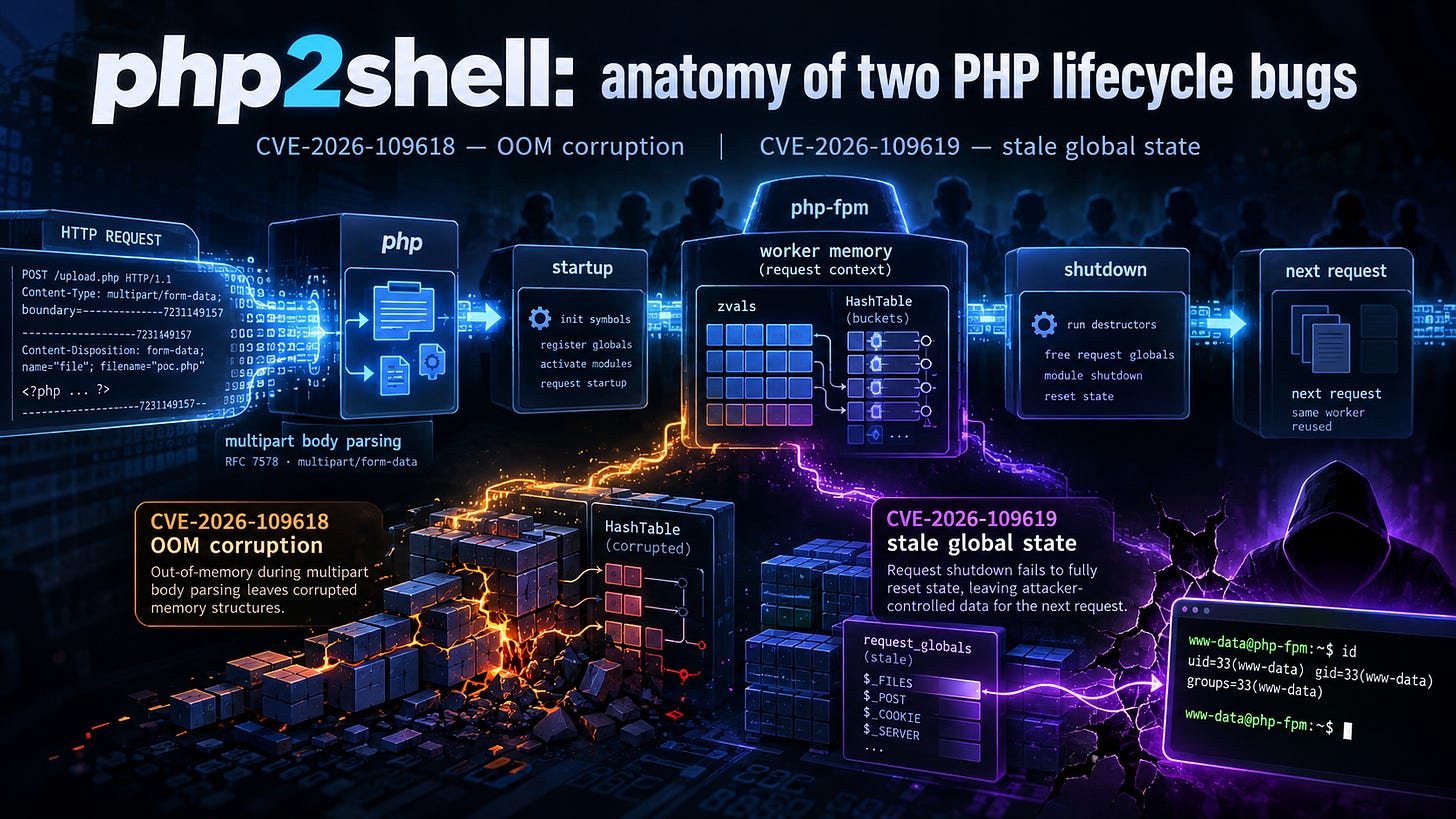
CVE-2026-109618, “RCE via OOM corruption”, is about what happens when PHP runs out of memory halfway through building a structure. The request is torn down mid-write, and the shutdown code goes on to trust whatever was left behind.

CVE-2026-109619, “RCE via stale global state”, is a use-after-free that spans two requests. One request leaves a worker-wide global pointing into its own heap, that heap is freed, and the next request on the same worker reads the global before anything has reset it.
Session upload progress turns up in both, which is how it ended up in the headlines and in the name, but it is a delivery mechanism and one consumer among several, not the root cause.
When an allocation pushes a request past memory_limit, the Zend memory manager raises a fatal error and bails straight out with longjmp(), abandoning whatever it was in the middle of. That is fine when the code it jumped out of had left its structures in one piece. It is a problem when the allocation that failed landed in the gap between a piece of memory becoming reachable and that memory being initialised.
Datadog’s writeup has the cleanest example of this. When PHP inserts a form field into a hash table, _zend_hash_str_add_or_update_i() bumps the table’s element counters before it allocates the new key. If the key allocation is the one that fails, the table now believes in a bucket that was never written. Nothing falls over yet. The payoff comes at request shutdown, when PHP destroys the table and walks every bucket it thinks it owns, reading uninitialised heap bytes as if they were zvals. Whatever an attacker managed to leave in that slot gets handed to destructor logic as a live value.
The obvious objection is that post_max_size exists precisely to stop a request getting this big, and the advisory walks through several ways around it during multipart parsing:
- A multipart request with no usable declared content length can clear the initial post_max_size check and keep feeding decoded body data anyway.
- A single part can carry an unbounded number of headers, and PHP’s in-memory representation of those headers is far heavier than their wire form.
- Empty file controls do not count against max_file_uploads but still build the usual file-metadata arrays, and nested field names multiply the work.
Datadog’s reproduction just used one form field name of about 3.5 MB to blow the limit during the key copy. All of it happens while the SAPI is still parsing the body, so no application code has run.
Whether the corrupted state is ever consumed depends on what the SAPI does once startup has failed. Apache mod_php runs the request shutdown procedure no matter what, even when request startup failed, so the half-built table always gets walked. That is what makes 618 fully application-independent on mod_php, and it is where full RCE was validated, with default input and memory limits at that. Source analysis puts FrankenPHP in the same boat.
PHP-FPM behaves differently. When php_request_startup() fails, FPM just exits the child, and the corrupted state dies with the process. FPM is still considered susceptible, because OOM can be reached after a clean startup inside an application path that does not expect the early exit, but nobody has demonstrated a complete FPM exploit.
CVE-2026-109619 needs a little vocabulary first. PHP keeps a lot of state in worker globals: error state, session state, decoder state, extension state. A persistent worker (an Apache prefork child, an FPM child) hangs onto those globals across requests, but much of what they point at lives on the per-request heap, which is torn down at the end of every request. The invariant is simple enough to state: every global pointing into request memory has to be reset before that memory is released.
The advisory frames the bug as a producer and a consumer. The producer is an operation that stashes request-owned state in a global and then gets interrupted before it can reset it, usually by a fatal error: OOM, a parse failure, Maximum execution time exceeded. A non-fatal diagnostic emitted late in shutdown can repopulate error state after it was already cleared, which gets you to the same place. Either way the request heap is freed with the global still pointing into it. The consumer is some operation on the next request on that worker that touches the global before normal request initialisation gets round to replacing it.
Two concrete cases.
The strongest is PHP 8.5’s fatal error backtraces. With fatal_error_backtraces on, a fatal error stores a request-owned backtrace in EG(last_fatal_error_backtrace), and the reset for it is always missed during shutdown. The consumer is any warning, notice or deprecation raised while PHP applies INI settings before executor initialisation, and that list is long: legacy assert.* on 8.3+, legacy session settings on 8.4+, explicitly set mbstring.* or iconv.* encodings, malformed quantities, paths rejected by open_basedir, and so on. The global gets read before PHP has even decided whether to report the warning, so error_reporting, @ and display_errors buy you nothing. On mod_php these settings come in through .htaccess and Apache php_value directives, applied before php_request_startup(); on FPM they come in through PHP_VALUE and PHP_ADMIN_VALUE from the frontend. This is the basis of the confirmed mod_php RCE.
The second is the session upload-progress lifecycle. Upload progress runs during body parsing, before ordinary session initialisation, and it doesn’t need the application to call session_start() at all. So it can play producer, publishing session and decoder state early, and it can play consumer, reading those globals on a later request before anything has reset them. On mod_php the producer, the fatal error and the next consumer can all land inside multipart startup. On FPM the validated path is a little longer: state published during normal application execution, then a fatal error, then upload progress as the early consumer on the following request. Wiz describe a memory disclosure out of the same family, where a stale PS(id) is trusted as a live string and URL-encoded into a PHPSESSID response cookie, leaking whatever now sits in that heap, which can be credentials and tokens from other requests.
Either way the attacker needs the producer and consumer requests to hit the same worker. More workers and worker recycling drop the per-attempt odds but don’t close the hole.
Before the advisories were out, several of us (0x4148’s lab is the most visible example) built a different model, and I built it too. The upload-progress callback, php_session_rfc1867_callback, caches two raw zval * pointers into the arData of arrays it builds, and php_session_rfc1867_update re-initialises $_SESSION once session.upload_progress.min_freq has elapsed. Stream a multipart body to php-fpm, stall for more than a second between chunks, and you can drive the callback through an update while those interior pointers are still live. Our PoC did precisely that, and confirmed the writes through the cached pointers by reading bytes_processed back out of the session file.
It never crashed, not even under AddressSanitizer with USE_ZEND_ALLOC=0, and 0x4148’s lab says exactly the same in its README. We chalked that up to the freed buffer not being dereferenced again before the request ended, and assumed heap grooming was the missing ingredient. The advisories have a blunter explanation: it was never the bug. Both real CVEs need a fatal interruption, and 619 needs a second request to the same worker, and a single well-behaved stalled upload gives you neither. The interior-pointer pattern in the callback is still worth a raised eyebrow as code, but php2shell doesn’t exploit it.
The pre-release claim that disabling upload progress only blocks one of the two bugs was right, as it happens, just not for the reason we assumed. The bug that isn’t gated by the setting is 618, the OOM corruption in body parsing, not some second dangling pointer buried in main/rfc1867.c.
Since the php2shell bundle was being passed around before disclosure, we pulled it apart statically before trusting a line of it. The Python is clean enough: no hidden C2, no exfiltration, no obfuscation, and every target defaults to localhost or whatever host the operator passes in. The big .zval.debug files aren’t binaries to run, they’re debug-symbol-only ELF objects (code sections marked NOBITS) whose only job is recovering a per-build symbol offset, so they go to readelf and nowhere near execution.
What makes the bundle worth writing about isn’t any of that. It’s that the whole thing turns out to be a string of plausible hallucinations: something that looks like a finished exploit, built almost entirely out of true parts, with the one piece that would make it real, an actual end-to-end code execution, quietly absent from the middle. The layers are worth taking one at a time, because they fail in the same way.
Start with the root cause, which is confidently wrong. The bundle finds the right callback and then builds a whole mechanism on top of it: orphaned serialize and unserialize context globals, a bailout before initialisation, a freed context block reused on the next request, line numbers and all. None of it is the bug the fixes address. The real pair are the OOM corruption in body parsing and the broad stale-globals class, with fatal error backtraces as the strongest confirmed case. It reasoned from the feature everyone was already talking about towards a mechanism that sounded right, which is the exact hole I fell into myself.
Then the “receipts”, which prove the vulnerable path is reachable and nothing past that. Read the stage map honestly and the deterministic proofs are all of the shape “request returns 500”, “worker survives”, “turn the feature off and it stops”. True, every one of them, and not one is code execution. The stage that would be, the actual RCE, wears its own “TUNED DEMO / ASLR brute required” label and admits in its own notes that it misses more often than it lands. A proof that collapses to one success in eight on the author’s own box, with nothing captured, isn’t a proof.
The precision is the seductive part and the least anchored. Byte offsets, spray sizes, a per-distro table of the distance between two symbols, leak values that “drift per run”, frames of video with shells on named CMS versions. Real exploits carry exactly this sort of detail, which is what makes it land, and not a byte of it is tied to a build you can rebuild and check. The video is the clearest case of the lot: a recording of a thing is not a reproduction of it.
And the tell I should have caught the first time round is the missing crash, explained away rather than believed. The bundle’s own lab never tripped AddressSanitizer, and instead of taking that as the result it is, it gets wrapped in a theory about which heap bin got reclaimed. A tidy answer stitched together from real function names, a real default-on feature and a real pre-userland window isn’t noise, and that is precisely why it reads as true and earns the opposite of trust. The honest verdict is a narrow one: the tool reliably reaches a vulnerable path and reliably kills workers, its stated root cause is wrong, and its claimed RCE is unproven in its own materials. It is still genuine offensive code, so it still only ever points at infrastructure you own.
Patching is the only complete fix, and both advisories say as much in bold. The fixed releases are 8.2.35, 8.3.36, 8.4.27 and 8.5.12, and PHP has published source backports for 7.4, 8.0 and 8.1, though a distribution may ship those without bumping the version string. The 618 patch takes longjmp() out of OOM handling entirely, swapping it for a soft limit raised at the next VM safe point and a hard limit that kills the worker with _exit(). The 619 patch resets the wider set of worker globals so none of them can survive into pre-initialisation code.
If patching has to wait, the configuration mitigations are per-path and partial. That last word matters:
- 618 OOM corruption
- Mitigation: memory_limit=-1, frontend body size limits, lower max_input_nesting_level, cap parts, headers and uploads
- Does not cover: an mmap() failure can still hit the vulnerable longjmp() path
- 619 fatal error backtraces (8.5)
- Mitigation: fatal_error_backtraces=0
- Does not cover: every other stale-state producer
- 619 session lifecycle
- Mitigation: session.upload_progress.enabled=0
- Does not cover: 618, and every non-session producer
- 619 in general
- Mitigation: remove per-request INI overrides that raise diagnostics, kill off reachable fatals, pm.max_requests=1 if you can wear it
- Does not cover: application and extension paths nobody has audited
Every one of these has to go in startup configuration with a restart of all workers behind it. session.upload_progress.enabled is INI_PERDIR, so ini_set() won’t touch it, and .user.ini is applied after normal initialisation, too late to matter for these paths. Don’t reach for RLIMIT_AS or RLIMIT_DATA to cap memory either; they make mmap() fail, which is the vulnerable path, not a defence against it. And it’s worth leaving upload progress off even after patching if nothing uses it, which the advisory itself suggests.
For detection, the signals worth watching are fatal “Allowed memory size … exhausted” errors logged against “Unknown on line 0”, form fields with absurd names, Apache AH00052 segfaults, oversized or malformed PHPSESSID cookies, and above all a web worker spawning a shell. A successful exploit can return HTTP 200 and leave the worker standing, so a clean crash log proves nothing.

Both CVEs are closed by a single commit, 31c0ea7, and its message is admirably blunt: “Replace bailout on OOM with UnwindExit” and “Properly reset various globals that may be accessed during startup”, one line per bug. It is a sprawling change, over a hundred source files, because the unsafe pattern was spread right across the tree, but the shape of it comes down to two ideas.
The first idea kills 618 at the root by making out-of-memory stop jumping. Before the patch, an allocation past the limit called longjmp() and tore straight out of whatever half-finished structure it was building. The fix adds a delayed-OOM state machine on the executor globals (EG(delayed_oom), a zend_oom_state of none/pending/handling/handled, and a ZEND_HAS_OOM() macro to test it) alongside a whole parallel family of fallible allocators, _femalloc() and friends, which return NULL on failure instead of bailing. The allocation sites that sit in the dangerous pre-initialisation window get switched to the fallible variants, so a failed allocation now unwinds through ordinary error returns and nothing is left half-built for shutdown to walk. Where the calling code genuinely can’t cope with a NULL, the OOM is recorded as pending and dealt with at the next safe point rather than mid-write: zend_call_function() now checks ZEND_HAS_OOM() on entry and again at its interrupt check, and if one is pending it calls zend_handle_delayed_oom(), throws, and returns FAILURE instead of letting the caller run on into corrupt state.
Backing that up is the soft/hard limit the advisory mentioned. main.c gains a memory_hard_limit_percent INI (defaulting to 200% of the limit when that limit is under 1 GB, or a flat 1 GB of headroom above it otherwise) and a ZEND_MM_MAX_ALLOCS ceiling. Cross the soft limit and you get the graceful delayed error; cross the hard one and the process is terminated outright with a distinct exit status (ZEND_MM_MAX_ALLOCS_EXIT_STATUS, 121) so an operator can tell a memory kill apart from an ordinary fatal. PHP keeps its ability to enforce a memory limit, it just never again uses the longjmp() that made enforcement dangerous.
The second idea closes 619 by resetting the globals a next-request consumer could read. The clearest hunk is in zend_shutdown_executor_values(), which now explicitly clears the exact state the advisory named as reachable before init_executor: EG(last_fatal_error_backtrace) is set back to undef, EG(record_errors), EG(num_errors), EG(errors), EG(error_handling) and EG(exception) are zeroed, and the user error and exception handlers are cleared, each carrying a comment along the lines of “may be used by zend_error_zstr_at before init_executor”. That is the fatal-error-backtrace producer and the early-INI-diagnostic consumer meeting in the source and finally being prised apart. php_request_shutdown() does the same for the request globals, setting PG(http_globals)[i] back to undef after the dtor (”May be accessed before php_request_startup()“) and calling clear_last_error(), and php_request_startup() now runs a new php_basic_early_rinit() so the basic-extension state, the session and serialisation globals at the heart of the upload-progress path, is re-initialised early rather than left stale. Even php_verror() now returns immediately when an OOM is pending, so error reporting can’t become the thing that trips over the broken state it was trying to report.
What I find quietly instructive is that the fix did not go hunting for the one vulnerable pointer we all chased before disclosure. It went after the class of bug: no unsafe jump out of a half-built structure, and no request-owned global left pointing at freed memory for the next request to find. The hundred-file diff is what treating the class rather than the instance actually costs.
Most of what this one leaves you with is about lifetimes crossing a boundary. PHP’s persistent worker is a long-lived process hosting short-lived request heaps, and every pointer that crosses from one to the other is a promise that someone will clean it up. Fatal errors and longjmp() are the paths that break those promises, because they skip the cleanup that ordinary control flow would have run. So if you go looking for the next one of these, don’t stare at a single callback. Look at every global that can be written before a fatal error and read before the next php_request_startup() finishes.
The bug taught me something about my own process too, and it taught it twice. I called it safe, then unreproducible, then built a tidy single-request model that happened to fit the feature in the headlines and the code I already had open. It reproduced something, which felt close enough to confirmation, and the one fact that cut against it, a complete absence of crashes, I explained away as missing heap grooming rather than treating it as the answer. When a vulnerability won’t reproduce, the instinct to trust is backwards: doubt the model, not the report. And when the model only half-reproduces, doubt it harder.
To read more about Keiran’s security thoughts, visit https://affixsec.substack.com/archive?sort=top